
Know exactly what your
prompt change broke.
EvalSprint runs every prompt version against the same test cases, checks each response with deterministic assertions, and shows which cases got fixed — and which quietly regressed.
Runs in your browser on the mock provider. No sign-up, no API key.
- Login outage is P1login-outage Fixed
- Billing issue without refund promiserefund-request Fixed
- Feature request is P3feature-request Regressed
-
contains "T-1003" — found at position 1matches /\bP3\b/ — no match in output
[T-1003] P2 — Customer asks for CSV export of the usage report. - Vague ticket asks for detailsvague-ticket Fixed
The problem
A prompt change is a code change. It just doesn't come with tests.
Silent regressions
Tightening one instruction fixes the case you were looking at — and breaks one you weren't.
Unrepeatable checks
Eyeballing outputs in a playground gives a different verdict depending on who looks, and when.
Scores without reasons
A single quality number says something changed. It doesn't say what, or why.
How it works
One suite file. Three steps.
Test cases live next to your prompts as plain JSON. The same file runs in the web app and the CLI.
-
1
Define cases
Each case supplies template variables and the assertions its output must satisfy.
"vars": { "ticket_id": "T-1002" }, "assertions": [ { "type": "contains", "value": "T-1002" }, { "type": "not-contains", "value": "we will refund" } ] -
2
Run a version
Every case is rendered, sent to the provider, and checked — with a reason for each result.
contains "T-1002" — substring not found in outputdoes not contain "we will refund" — forbidden substring found at position 45matches /\bP[23]\b/ — no match in output -
3
Compare versions
Run two versions on the same cases to see what a change fixed — and what it broke.
Billing issue…Feature request…
Assertions
Checks that explain themselves.
Five deterministic assertion types. A case passes only when every assertion passes, and each result tells you exactly why.
- Same input, same verdict — no model grading the model.
- Invalid regexes and missing variables are caught before anything runs.
- Case-sensitivity, trimming and regex flags are explicit.
contains"T-1002"
found at position 1
not-contains"we will refund"
forbidden substring found at position 45
equals"yes"
output matches exactly
regex/\bP[23]\b/
no match in output
max-length200
output is 61 characters
Prompt comparison
Every case, before and after.
Both versions run against identical cases and assertions. You get the pass-rate delta, a per-case transition, and both outputs side by side.
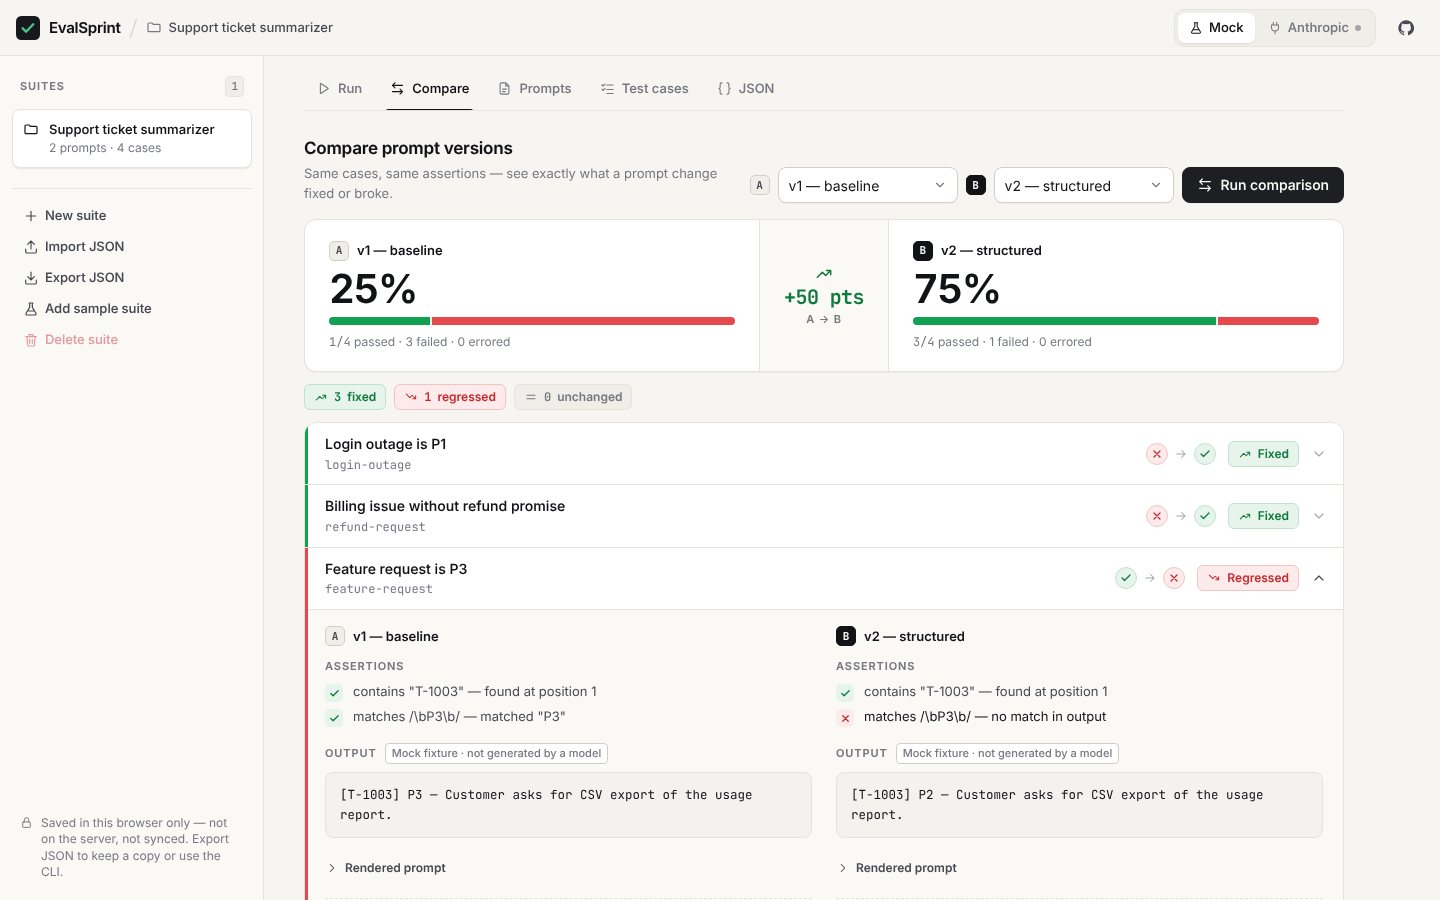
Pass-rate delta
A single number for the change, backed by the cases that moved it.
Per-case transitions
Each case is marked fixed, regressed or unchanged — regressions are never averaged away.
Both outputs, side by side
Expand any case to see each version's output and assertion results together.
Providers
Start free and deterministic.
Add a real model when you're ready.
Mock
Default · no key needed- Returns fixture outputs written into the suite
- Free and fully repeatable — ideal for CI and demos
- Clearly labelled as not generated by a model
- Can simulate provider errors with
!error:fixtures
Anthropic
Optional · your own instance- Real calls through the official Anthropic SDK
- API key read from the server environment only
- Latency, tokens and model recorded only when reported
- Clear messages for auth, rate-limit and model errors
The public demo runs the mock provider only — Anthropic is disabled on its server regardless of configuration.
CLI
Same engine in your terminal and CI.
The CLI runs the exact suite file you edit in the app — init, validate, run and compare.
- 0
- every case passed
- 1
- a case failed or errored
- 2
- usage or config error
Add --json for machine-readable results.
$ npm run evalsprint -- compare \
    examples/support-tickets.json --a baseline --b structured

Compare: v1 — baseline  vs  v2 — structured

  Login outage is P1                    fail  → pass   fixed
  Billing issue without refund promise  fail  → pass   fixed
  Feature request is P3                 pass  → fail   regressed
  Vague ticket asks for details         fail  → pass   fixed

  A baseline: 1/4 (25%)
  B structured: 3/4 (75%)  +50 pts
$ echo $?
1
Quick start
Running locally in a minute.
Requires Node.js 20.12+. The mock provider works immediately; set ANTHROPIC_API_KEY in your server environment to make real model calls.
$ git clone https://github.com/bhargavthaparbusiness/evalsprint.git
$ cd evalsprint && npm install
$ npm run dev$ npm run evalsprint -- init my-suite.json
$ npm run evalsprint -- run my-suite.jsonSee a regression get caught.
The app opens with a sample suite and two prompt versions. Run it, compare them, then make it yours.